Latency Optimization
Introduction
Voice agents and real-time applications rely on consistently low latency. This page explains how to use streaming output, how to correctly measure latency, and what you can do to reliably achieve ~100 ms first-byte response times with Murf Falcon 2.
How to Use Streaming Output
With streaming output, you don’t need to wait for the entire audio response or write it to a file before playback. Instead, process and play each audio chunk as soon as the server delivers it.
Below are example code snippets showing how to test and play streaming audio:
HTTP Streaming
WebSockets
We also recommend integrating Falcon 2 directly into your agent infrastructure when testing streaming output. For the fastest and simplest setup, use the Murf plugins, which are optimized for low latency.
How to Measure Latency
Streaming & WebSocket Endpoints
Both Streaming and WebSocket endpoints deliver audio incrementally. To measure latency correctly, the key metric to track is Time to First Audio Byte. This is the only metric that reflects true real-time performance.
Understanding Latency Components
- Time_namelookup: This is the time spent resolving DNS. It can be reduced through OS-level DNS caching or by using long-lived processes that avoid repeated lookups.
- time_connect: This represents the TCP handshake. You can reduce it by reusing connections and enabling keep-alive agents.
- time_appconnect: This is the TLS handshake time. It can be improved by using TLS 1.3 and leveraging persistent TLS sessions.
- time_starttransfer: This measures how long it takes for the server to send the very first byte of audio. This is the most important indicator for streaming performance. You can lower it with proper streaming usage and by sending shorter text chunks.
- time_total: This is the full time required to receive the entire response. For real-time applications, this metric is not critical. Focus instead on first-byte latency.
Measuring Latency with curl
You can inspect all timing components using the curl -w formatter:
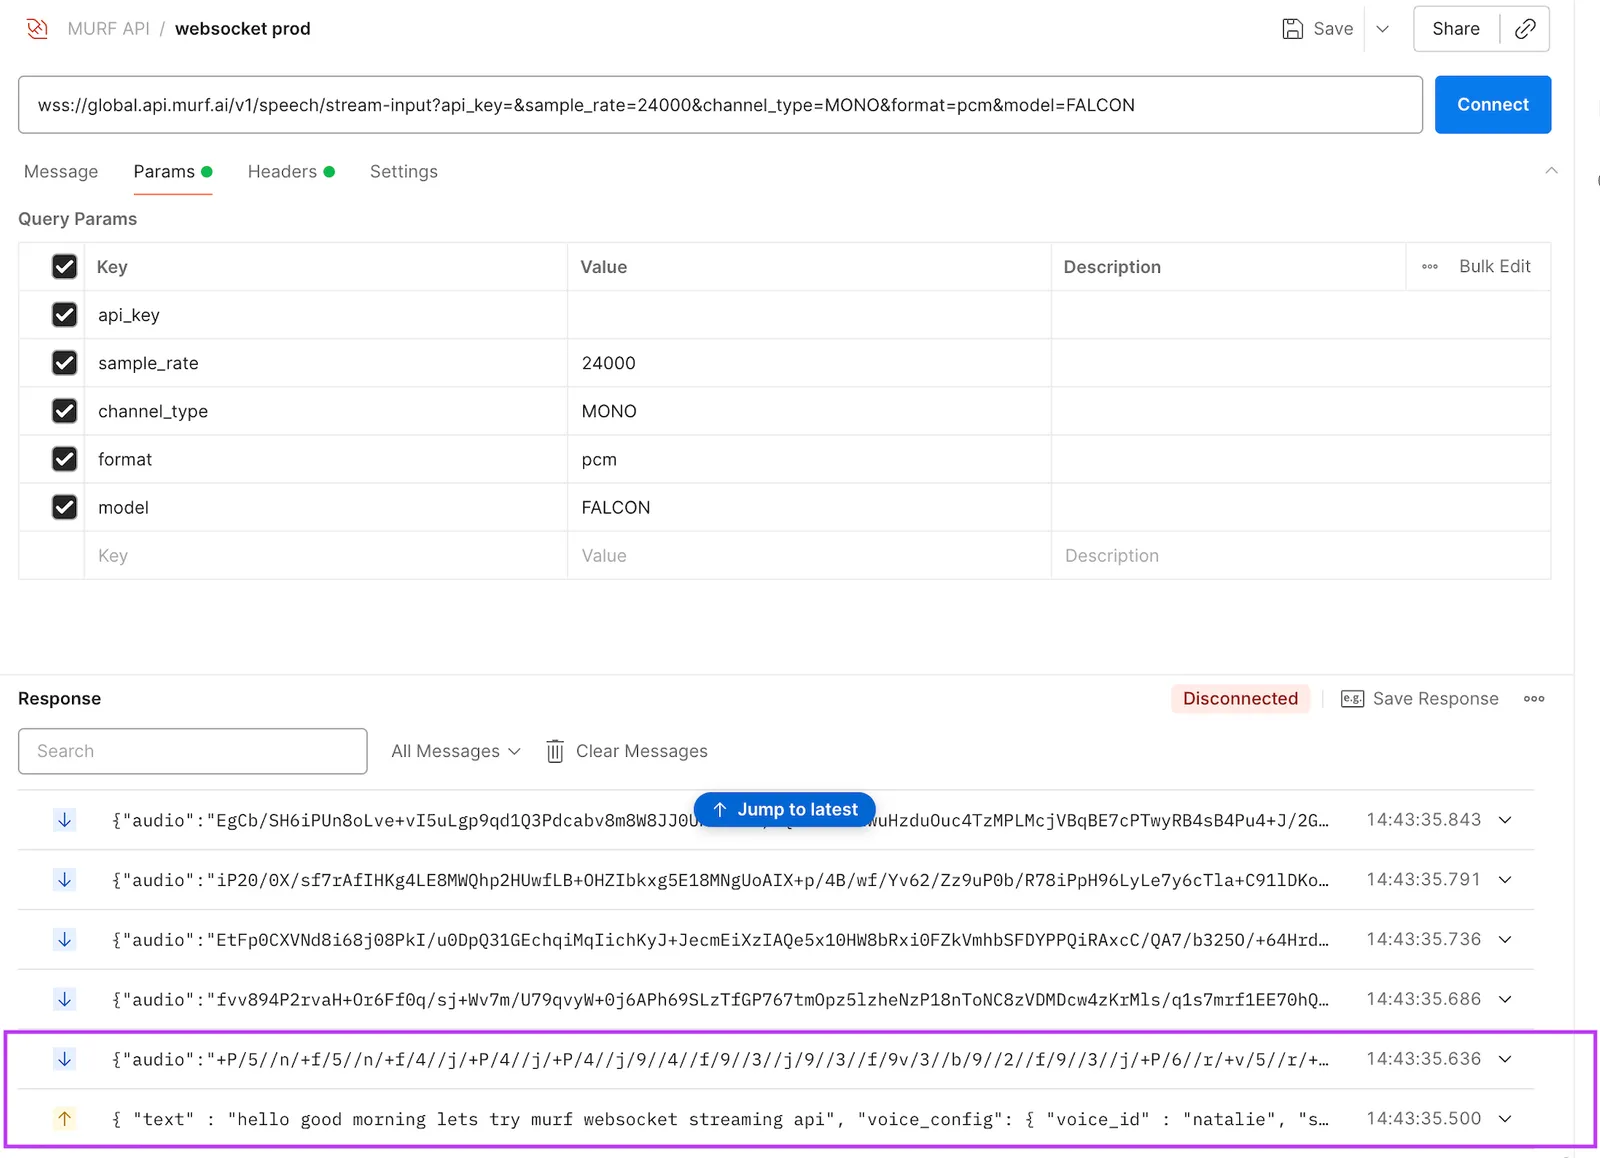
Measuring Latency with Postman
If you prefer a UI-based method, Postman also provides a simple way to measure latency. After you send a request, Postman shows the request duration directly in the response window. This value represents how long it took for Postman to receive the first byte of the response.
Best practices to achieve lowest latency
1. Client Location
Murf provides Falcon 2 deployment in 11 global regions. For best performance, you should:
- Choose the region closest to your infrastructure, or
- Use the Global Endpoint, which automatically routes your request to the nearest available Murf region.
This ensures your request travels the shortest possible distance, giving you the fastest achievable first-byte latency.
For example, if your agent is hosted in AWS us-east-2, choosing the same Murf region minimizes RTT. If you’re testing from Europe or India, the global endpoint will route you to the nearest region automatically.
Recommendation:
Use the global endpoint for routing the request to the nearest region automatically. Below are regional urls for Falcon 2 streaming endpoint.
2. Client Environment
Latency depends heavily on where your request originates. Your client (browser or server) must send a request to Murf’s servers and wait for the first audio byte to come back. The physical distance and network path directly affect round-trip time (RTT).
Browser vs. Server
When you test from a browser, your local machine becomes the client. This means latency will include:
- Your home/office network quality
- Your ISP routing
- Distance from your physical location to Murf’s servers
- Wi-Fi instability, VPNs, or proxies
As a result, browser tests usually show higher and more variable latency. However, in production your voice agent will typically be hosted on a server, such as AWS, or GCP. Servers in major cloud regions have:
- Much lower network hop counts
- Direct peering to hyperscalers
- Highly stable routing paths
This results in significantly lower and more consistent latency.
Recommendation:
To understand real-world performance of your agent, always measure latency from the same environment where the agent will run, ideally a cloud server, not your local laptop.
3. Language & Script Considerations
Some languages require additional preprocessing or have inherently higher synthesis complexity, which can add a 10-20 milliseconds to first-byte latency. You can minimize this by using the right script and optimizing input text.
Best Practices:
Use the correct script for each language
For Hindi, always prefer Devanagari (देवनागरी) instead of Latin transliteration. This reduces preprocessing and results in lower latency and more accurate pronunciation. If you send Hindi written in English characters (“aap kaise ho”), the system currently performs transliteration, which adds 5–10 ms of overhead.
Examples:
-
Hindi — Devanagari (देवनागरी)
- Recommended: “आप कैसे हैं?”
- Not recommended: “aap kaise hain?”
-
Tamil — Tamil script (தமிழ்)
- Recommended: “நீங்கள் எப்படி இருக்கிறீர்கள்?”
- Not recommended: “neenga eppadi irukeenga?”
-
Telugu — Telugu script (తెలుగు)
- Recommended: “మీరు ఎలా ఉన్నారు?”
- Not recommended: “meeru ela unnaru?”
-
Kannada — Kannada script (ಕನ್ನಡ)
- Recommended: “ನೀವು ಹೇಗಿದ್ದೀರಿ?”
- Not recommended: “neevu hegiddiri?”
-
Bengali — Bengali script (বাংলা)
-
Recommended: “আপনি কেমন আছেন?”
-
Not recommended: “apni kemon achhen?”
-
-
Marathi — Devanagari (देवनागरी)
-
Recommended: “तू कसा आहेस?”
-
Not recommended: “tu kasa ahes?”
-
-
Gujarati — Gujarati script (ગુજરાતી)
-
Recommended: “તમે કેમ છો?”
-
Not recommended: “tame kem cho?”
-
For code-mixed text such as Hinglish, and for how to write numbers, dates and codes, see Best Practices.
4. Use Connection Pooling (Persistent Connections)
Reusing connections avoids repeated TCP and TLS handshakes, which significantly reduces first-byte latency.
- Python: use
httpx.AsyncClient()orrequests.Session()to keep connections warm. - WebSockets: Keep one socket open for the whole call and send every turn on it.
Persistent connections help you avoid 30–80 ms of extra overhead per request, especially in real-time voice workloads.
5. Let Falcon Handle Chunking (WebSockets)
Over WebSockets, Falcon waits for each sentence to end, marked by punctuation, before it generates audio. Two things affect how long that wait is: whether anything else splits the text first, and how Falcon handles ambiguous endings.
Turn off chunking in your voice agent framework
If you’re building with a framework such as LiveKit or Pipecat, turn off its sentence tokenizer or text aggregation and stream LLM tokens straight to Falcon’s WebSocket. When the framework splits sentences and Falcon splits them again, each layer adds its own wait. Letting Falcon do the splitting on its own gets audio started sooner.
Use predictive chunking
Some endings are hard to call, like 2 p.m. or Dr., and by default Falcon waits for one more character before deciding. If you set predictive_chunking to lenient, Falcon starts straight away in those cases, which brings first-byte latency down for voice agents.
See Advanced Settings for buffer settings and word timestamps.