WebSocket
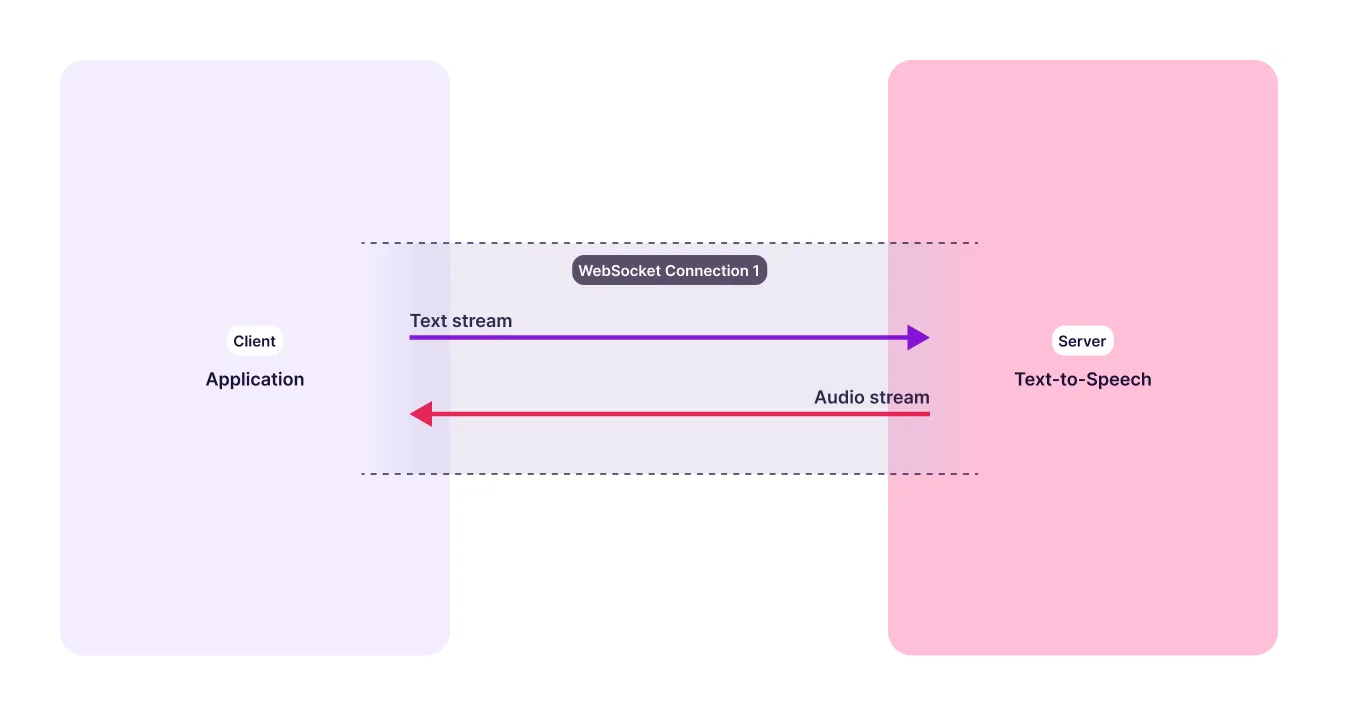
Murf TTS API supports WebSocket streaming, enabling low-latency, bidirectional communication over a persistent connection. It’s designed for building responsive voice experiences like interactive voice agents, live conversations, and other real-time applications.
New: Pass model = falcon-2.1 to use our Falcon 2.1 model in text-to-speech
streaming endpoints, designed for ultra-low latency (~100 ms). WebSocket
streaming supports Falcon only.
With a single WebSocket connection, you can stream text input and receive generated audio continuously, without the overhead of repeated HTTP requests. This makes it ideal for use cases where your application sends or receives text in chunks and needs real-time audio to deliver a smooth, conversational experience.
Endpoint
global geo-routes your connection to the nearest datacenter. Use it unless you have a data-residency requirement, in which case pin to a regional host such as wss://in.api.murf.ai/v1/speech/stream-input — see Available Regions for the full list.
api.murf.ai is a legacy alias that always resolves to us-east and does not
geo-route. Note also that /v1/speech/stream-input is the WebSocket path;
/v1/speech/stream is the HTTP streaming endpoint.
Quickstart
This guide walks you through setting up and making your first WebSocket streaming request.
Getting Started
Generate an API key here. Store the key in a secure location, as you’ll need it to authenticate your requests. You can optionally save the key as an environment variable in your terminal.
Install required packages
This guide uses the websockets and pyaudio Python packages. The websockets package is essential for the core functionality.
Note:
pyaudiois used in this quickstart guide to demonstrate playing the audio received from the WebSocket. However, it is not required to use Murf WebSockets if you have a different method for handling or playing the audio stream.
pyaudio depends on PortAudio, you may need to install it first.
Installing PortAudio (for PyAudio)
PyAudio depends on PortAudio, a cross-platform audio I/O library. You may need to install PortAudio separately if it’s not already on your system.
macOS
Linux (Debian/Ubuntu)
Windows
Once you have installed PortAudio, you can install the required Python packages using the following command:
Choosing a voice
Pick a voice from the Falcon 2.1 list in the Voice Library. Falcon 2.1 voices are for realtime agents.
What matters is that the voice exists in the Falcon 2.1 catalog. An unknown voice returns an INVALID_VOICE error with "fatal": true, and the message points you to GET /v1/speech/voices?model=falcon-2.1.
Using voice settings with Context IDs
A context_id does not alter the values in voice_config; it determines which
independent context owns those settings. If you include a context_id on a
text frame, send a voice_config frame with the same context_id first.
A configuration sent without context_id belongs only to the default context,
so named contexts do not inherit it. Text sent to an unconfigured named
context uses the default voice and produces a NO_VOICE_CONFIG warning. The
context keeps its configured settings for its lifetime, even if you later
change the default context’s configuration.
For a single default stream, you can omit context_id from both frames. See
Context ID for multi-turn and
interruption examples.
Audio format and the WAV header
With format=WAV, the first audio chunk of a context starts with a 44-byte WAV header whose RIFF-size and data-size fields are 0xFFFFFFFF — the “length unknown, read to end of stream” sentinel — because the total length isn’t known mid-stream. Only the first chunk has it.
- Playing progressively: feed the bytes straight to a streaming decoder. It honours the sentinel.
- Saving to a file: strip the first 44 bytes, concatenate the rest, then write your own header with the real length. Otherwise players show a bogus duration and can’t seek.
- Avoiding it entirely: request
format=PCMfor headerless little-endian 16-bit samples.
Field naming
Request fields accept both snake_case and camelCase (context_id/contextId, min_buffer_size/minBufferSize, max_buffer_delay_in_ms/maxBufferDelayInMs, predictive_chunking/predictiveChunking, add_word_timestamps/addWordTimestamps). Responses are always snake_case.
Note that voice_config itself uses camelCase inside (voiceId, volumeOffset, and other voice settings), which is why both spellings are accepted at the top level.
predictive_chunking, min_buffer_size, max_buffer_delay_in_ms and
add_word_timestamps are top-level siblings of text, not members of
voice_config. Nesting them inside voice_config fails silently. See
Advanced Settings.
Machine-readable schema
Every frame, field and query parameter is defined in the WebSockets API reference, generated from our AsyncAPI document. Use it when generating a client.
Available Regions
Use the region closest to your users for the lowest latency.
The Global Router picks the nearest region automatically. The
concurrency limit is 5 for US-East and 2 for all other regions.
Each final message tells you the serving region and your current usage;
see Check your usage.
For a higher limit, use the US-East endpoint directly or contact us to
raise limits for regional endpoints.
Best Practices
Following are some best practices for using the WebSocket streaming API:
- Send
voice_configbefore anytext. When using a named context, put the samecontext_idon both frames. Text that arrives in an unconfigured context is generated with the default voice and returns aNO_VOICE_CONFIGwarning. - Branch on
error_codeandwarning_code, never on the human-readable message. See Errors & Warnings. - Once connected, the session remains active as long as it is in use and will automatically close after 3 minutes of inactivity.
- You can maintain up to 10X your streaming concurrency limit in WebSocket connections, as per your plan’s rate limits & concurrency.
- Keep active contexts below your limit. Going over it closes the connection with code 4029. Watch the
concurrencyobject on eachfinalmessage, or connect withinclude_usage=true. See Rate Limits & Concurrency. - For the lowest latency, prefer Falcon 2.1 voices by setting model =
falcon-2.1. - If you use LiveKit or Pipecat, turn off the framework’s sentence tokenizer or text aggregation and stream LLM tokens straight to the WebSocket. Falcon does its own sentence splitting.
- For how to write text for Falcon, including numbers, codes, scripts and an LLM system prompt template, see Best Practices.
Next Steps
FAQs
How is WebSocket streaming different from HTTP streaming in the Murf TTS API?
WebSocket allows you to stream input text and receive audio over the same persistent connection, making it truly bidirectional. In contrast, HTTP streaming is one-way, you send the full text once and receive audio while it is being generated. WebSocket is better for real-time, interactive use cases where text arrives in parts.
What format is the audio received over WebSocket?
The audio is streamed as a sequence of base64-encoded strings, with each
message containing a chunk of the overall audio. With format=WAV, only the
first chunk of a context carries a 44-byte header, and its length fields are
placeholders. Request format=PCM to receive headerless little-endian
16-bit samples instead.
After how long will the WebSocket connection close due to inactivity?
The WebSocket connection will automatically close after 3 minutes of inactivity.
What features can I use with the WebSocket Streaming API?
Voice, locale, speed, and pitch are available. Falcon 2.1 style is
Conversational only; style control is on
Styles.
Set how any word is pronounced by writing it in IPA in your text
("/mɜːrf/") or with pronunciation_dictionary in voice_config. You can
also tune latency with predictive chunking and receive word-level timestamps.
See Advanced Settings.
Custom pause tags, audio duration, and variations are not supported.
How do I enable Falcon 2.1 over WebSockets, and who should use it?
Add model = falcon-2.1 to your WebSocket connection query (or request
parameters). Falcon 2.1 is optimized for ultra-low latency (~100 ms) and is
ideal for interactive agents, live support, gaming, tutoring, and other
real-time experiences where fast turn-taking matters. WebSocket streaming
supports Falcon only.
What happens if my API key is invalid?
The HTTP upgrade completes and the connection is then closed with WebSocket code 1008 (policy violation). It is not an HTTP 401, so handle the close code. See Errors & Warnings.